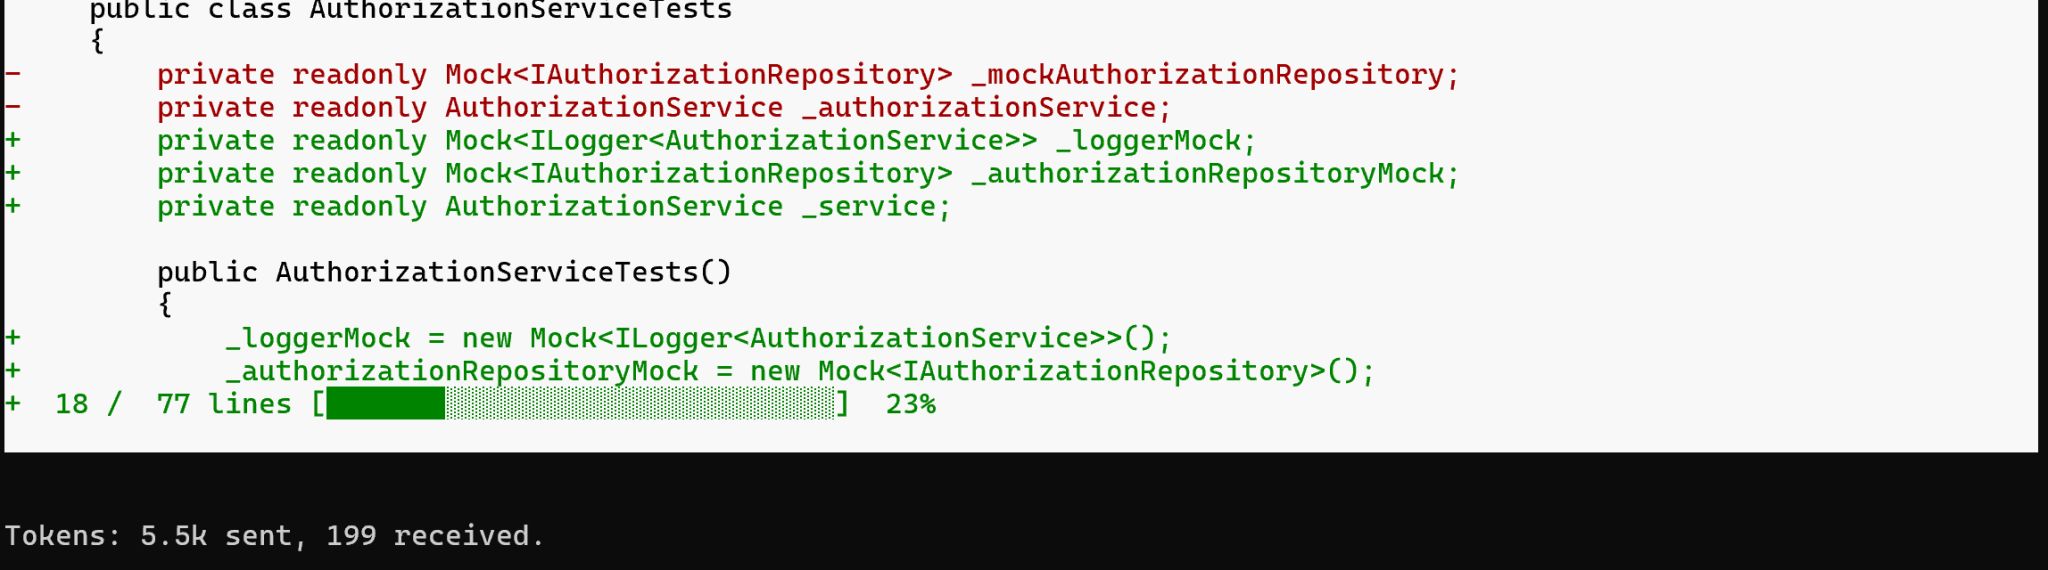
After waiting nearly a year for decent local LLM support on Intel GPU (especially after IPEX-LLM stalled in April 2025), I was excited to see Foundry Local reach General Availability recently. I hoped it could finally become a solid Ollama replacement for my Intel GPU setup.
Reality check after testing today with Aider:
DeepSeek-R1-Distill-Qwen-14B-openvino-gpu:2 was hard-capped at 199 tokens (config.json max_tokens: 16k completely ignored). Not usable.
qwen2.5-coder-14b-instruct-openvino-gpu:2 also capped at 199 tokens, code snippets and responses get cut off before finishing. For agentic coding workflows like Aider, this token limitation is a major blocker.
Has anyone managed to get reasonable context lengths with OpenVINO models in Foundry Local? Any tips or workarounds?